Tuesday, October 20, 2020

Pomposity!

Let $f(x)$, $f \in \mathrm{C}^{\infty}$, be the following infinitely continuously differentiable function over the space of real numbers:
\[ 
f(x) \doteq 
\sum_{n=0}^{\infty} \frac{e^{-2} \, 2^n}{n!}
+ \frac{1}{\sqrt{2 \, \pi}}\int_{-\infty}^{+ \infty} x  \, \exp(-y^2/2) \, dy;
\]
then, applying Taylor's theorem and the Newton–Leibniz axiom,
\[f(1) = 2.\]
Time out! What the Heck?!?!

Okay. Breathe.

Let's restate the above in non-pompous terms.

Let $f(x)$ be the following function
\[f(x) = 1 + x\]
then $f(1) = 2$.

All the words between "following" and "function" in the first paragraph mean "smooth," which this function certainly is; $f \in \mathrm{C}^{\infty}$ is the formal way to say all the words in that sentence, so it's redundant. 
 
As for the complicated formula, it uses a series and an integral that each compute to one. Eagle-eyed readers will notice that the first is the Taylor series expansion of $e^2$ times the constant $e^{-2}$ and the second is $x$ times the integral of the p.d.f. for the Normal distribution for $y$, which by definition of a probability has to integrate to 1. Taylor's theorem and Newton–Leibniz axiom are used to get the values for the series and the integral from first principles, as is done in first-year mathematical analysis classes, and which no one would ever use in a practical calculation.

I took a trivially simple function and turned it into a complicated, nay, scary formula. With infinite sums, integrals, and theorems. Taylor is relatively unknown, but Newton and Leibniz? Didn't they invent calculus? (Yes.) So my nonsensical formula acquires immense gravitas. Newton! And Leibniz!!

And that's the problem with an increasing number of public intellectuals and technical material.

There are some genuinely complex things out there, and to even understand the problems in some of these complex things one needs serious grounding in the tools of the field. There's no question about that. But there's a lot of deliberate obfuscation of the clear and unnecessary complexification of the simple.

Why? And what can we do about it?


Why does this happen? Because, sadly, it works: many audiences incorrectly judge the competence of a speaker or writer by how hard it is to follow their logic. And many speakers and writers thus create a simulacrum of expertise by using jargon, dropping obscure references and provisos into the text, and avoiding simple, clear examples in favor of complex and hard-to-follow, "rich," examples.

What can we do about it? This is a systemic problem, so individual action will not solve it. But there's one thing we each can do: starve the pompous of the attention and recognition they so crave. In other words, and in a less pompous phrasing, when we realize someone is purposefully obfuscating the clear and complexifying the simple, we can stop paying attention to them. 

Simplicity actually requires more competence than haphazard complexity; it requires the ability to separate what is essential from what's ancillary. To make things, as Einstein said, as simple as possible, but no simpler.

It's also a good thinking tool for general use. Feynman describes how he used to follow complicated topological proofs by thinking of balls, with hair growing on them, and changing colors:

As they’re telling me the conditions of the theorem, I construct something which fits all the conditions. You know, you have a set (one ball)—disjoint (two balls). Then the balls turn colors, grow hairs, or whatever, in my head as they put more conditions on. Finally they state the theorem, which is some dumb thing about the ball which isn’t true for my hairy green ball thing, so I say, “False!”

If it’s true, they get all excited, and I let them go on for a while. Then I point out my counterexample.

“Oh. We forgot to tell you that it’s Class 2 Hausdorff homomorphic.”

“Well, then,” I say, “It’s trivial! It’s trivial!” By that time I know which way it goes, even though I don’t know what Hausdorff homomorphic means.

Excerpt From: Richard Feynman, “Surely You’re Joking, Mr. Feynman: Adventures of a Curious Character.”

Let's strive to be like Einstein and Feynman.


- - - - -
This post was inspired by an old paper that starts with $1+1=2$ and ends with a multi-line formula, but I've lost the reference; it might have been in the igNobel prizes collection.

Sunday, October 18, 2020

Of martingales and election forecasts

(This post started its life as a response to a video, but during its development I decided that there's enough negativity in the world, so it's now a stand-alone post.)


What are these martingales?

Originally a gambling strategy, martingales are discrete-time stochastic processes... hold on, I sound like the person in that video: pompous, jargon-spewing, and unhelpful.

Let's say we have some metric that evolves over time, like the advantage candidate A (for Aiden) has over candidate B (for Brenna) in an election in the fictional country of Zambonia, and that we get measures of this metric at some discrete points (every time we take a poll, for example). Note that these are a sequence of points, ordered, but not necessarily equidistant. That's what discrete-time means, that the "independent variable" (time) is ordinal but not cardinal.

(This makes a difference for many models; in actual electoral metrics it's not very important since most campaigns run daily tracking polls.)

So, we have a metric, say $A_i$, the point advantage of Aiden in poll number $i$. This is just a sequence of numbers. If they come from an underlying process which includes some unobservable or random parts we say that the $A_i$ follow a stochastic process. (Stochastic is a [insert Harvford tuition here] word for random.)

A discrete-time stochastic process is a martingale if the best estimate we have for the metric in the future is the current value, in other words,

\[ E[A_{i+1}] = A_i. \]

In some sense, we already sort-of assume that the elections are some sort of martingale: we treat the daily poll as the best estimate of the future results. Well, we used to. Some people still do, and add a lot of unsupported assumptions to develop option pricing models for... oh, bother, almost got into that negativity again.


Martingales and forecasting

A simple example of a martingale is a symmetric random walk,

\[A_{i+1} = \left\{ \begin{array}{ll}   A_i + a & \text{ with prob.  1/2} \\  A_i - a & \text{ with prob. 1/2} \end{array}\right.\]

Here are two examples, with different $a$, to show how that parameter influences the dispersion.


We can see from that figure that despite the current value being the best estimate of future values, we can make serious errors if we don't consider that dispersion. Consider the red process and note how bad the values for $A_{13}$ (POINT A) and $A_{41}$ (POINT B) are as estimates of the final value. Note also that $A_{13}$ is closer to the final value than $A_{41}$  despite $A_{41}$ being much farther along in the process (and therefore its $i=41$ is closer to the final $i=66$ than $i=13$).

Another example of a martingale is $A_{i+1} = A_i + \epsilon$ where $\epsilon$ is a Normal random variable with mean 0 and standard deviation $\sigma$. Using a standard Normal, $\sigma = 1$, here are two examples of this process:


Note how despite the same parameters and starting point, the processes' evolution is quite different. This becomes more obvious when the processes have different standard deviations:


The main point here is that even though martingales appear very simple, in that the best estimate for the future is the current value of the metric, the actual realizations of the future may be very different from the current metric.

That alone would be a good reason to try to find better ways to model elections. However this is not the only, or even the best argument against models of elections using martingales. As Ron Popeil used to say:


But wait, there's more!

The real argument here is that the process of interest (who people will vote for) and the process being measured (who the people who are willing to answer poll questions say they'll vote for) are not the same.

What's primarily wrong is that the information being used to create the $A_i$ at any point isn't an unbiased measure of the probability of Aiden winning. And that's not on the math, that's on (a) polling technique and (b) political use of polls.

Polling technique depends on people's answers, usually corrected with some measures of demographics and representativeness. For example, if Zambonia has 20% senior citizens and the polling sample only has 10%, that has to be accounted for with some statistical corrections.

Another correction comes from noticing, for example, that in previous elections the model was off by some percentage and dealing with that: if the polls for Zamboni City had Clarisse winning by 10% in the last elections but Hannibal won Zamboni City by 5%, that response bias needs to be corrected, somehow, in newer models.

Political use of polls happens when results that are known to be biased are released for political reasons. For example Aiden may release what their campaign knows to be wrong numbers to discourage Brenna donors, volunteers, and voters.

So, the problem with using martingales as a model of the election is that the information being used to generate the metrics being tracked is not an unbiased representation of the underlying reality. It's possible that the dynamics of the metric are a martingale, but what the metric is measuring is not the electoral vote but a mix of socially acceptable answers (who wants to say they're voting Hannibal rather than Clarisse, even when they are?) and push-poll results designed to influence the electoral process

Many professional political forecasters deal with this mismatch using field-specific knowledge and heuristics. Certain others criticize them for the heuristics and field-specific knowledge while missing the problems implicit in using martingale-based models.

Good, no Taleb references at all. 🤓


Recommendation: readers interested in political (and other) forecasting might want to read Superforecasting, by Phil Tetlock and Dan Gardner.

Saturday, October 3, 2020

More Talebian nonsense: eyeball 1.0 vs statistics

Apparently Nassim Nicholas Taleb* doesn't like some paper in psychology and decided to debunk it using a very advanced technique called "can you tell the difference between these graphs?"

Yes, the Talebian method is to look (with eyeball 1.0) at 2-D graphics and his argument is that if we can't tell the difference between a graphic with uncorrelated data and one with a small effect size, then we should dismiss the paper.

Wait, that's not entirely accurate. That rationale only applies to papers that have conclusions Taleb disagrees with. As far as I know, NNT hasn't criticized the massive amount of processing that was necessary to come up with the "photo" of the Messier 87 supermassive black hole from the raw data of the Event Horizon Telescope.

No, the "use your eyeball" method applies selectively to papers NNT doesn't like; and apparently his conclusions then apply to an entire field (psychologists, who NNT seems to have a problem with, minor exceptions allowed).

Okay, so what's wrong with this logic? 

Everything!

The reason we developed statistical analysis methods is because our eyes aren't that good at capturing subtle patterns in data when they are there.

Here are two charts plotting three variables pairwise. Can you tell which one has a correlation?


(C'mon, don't lie; you can't and neither can I — and I made the charts.)

Here, we'll fit an OLS model to the data. Now, can you tell?


(You should; the line on the left has a 10% grade; and as anyone who's ever tried to bike a long 10% grade street knows, that's a lot steeper than you'd guess.)

The thing is, there's no noise in that data; what appears to be noise is simply a missing factor, an artifact created because you can't really represent three continuous variables on a 2-D flat plot. (You can use a 2-D projection of a 3-D surface and move it around with a cursor to simulate 3-D motion, but that's not really the point here.)

That data is $Y = 0.1 \times X + Z$; note how there's no error in it. $X$ and $Z$ have some variability, but are uncorrelated. $Y$ is determined (with no error) from $X$ and $Z$, but when we plot $Y$ on $X$, the variation due to the missing variable $Z$ obscures the more subtle variation due to $X$.**

This is why we use statistical methods to elicit estimates, rather than eyeball 1.0.

- - - - -

* When one tracks topics like statistics, sometimes one gets a link to Nassim Nicholas Taleb making a fool of himself. I only watched the first couple of minutes until NNT unveils his Mathematica-based illustration, at which point his argument was already clear. And clearly wrong.

** I have two chapters in my (coming soon) book on missing factors, by the way. 🤓


Friday, September 11, 2020

Theory vs Experiments and Frequentists vs Bayesians

This is part of the ongoing book project, though it might be offloaded into a technical notes supplement, since it requires a bit of calculus to follow completely. Clearly this book is targeted at a mass market.


A good theory versus A-B testing to exhaustion


There's nothing more practical than a good theory.

Coupled with experimental measurement of the relevant parameters, of course.

But this is very different from the ``let's just run an experiment'' approach of many theory-less areas (or areas that have ``theories'' that don't describe the real world, but are just coordinating devices for in-group vs out-group signaling, as can be found in certain fields in academe suffering from serious Physics-envy).

Our illustration will be how to calculate how long it takes a mass to drop from height $h$, in negligible atmosphere, in a planet with gravity $g$ (not necessarily Earth). 

The "A-B testing to exhaustion" approach would be: for any height $h$ that we care about, run a few, say 100, test drops; average (or otherwise process) the resulting times; and report that average. This would require a new set of test drops for each $h$, just like A-B testing (by itself) requires testing each design.

The advantage of having a working theory is that we don't need to test each $h$ or design. Instead we use experiments to calibrate estimates for important parameters (in the example, the gravity) and those parameters can then be used to solve for every situation (the different heights of the drop).

Note that if we want to interpolate across different $h$ we would need a theory to do so; simple (linear) interpolation would be wrong as the time is a non-linear function of height; the non-linearity itself would be evident from a few values of $h$, but the standard empirical generalization attempt of fitting a polynomial function would also fail. (It's a square root; naughty example, isn't it?)

Yes, it's either theory plus calibration or a never-ending series of test drops. So let's use theory.

We know, from basic kinematics that $h = g t^2/2$, so the time it takes for a mass to drop from a height $h$, given the gravity $g$ of the planet, is

\[t(h;g) = \sqrt{2h/g}.\]

So what we need, when we arrive at a given planet, is the $g$ for that planet. And that brings up the measurement problem and one big difference between frequentists and Bayesians.

Let's say we use a timed drop of 1 meter and get some data $D$, then compute an estimate $\hat{g}$ from that data. Say we dropped a mass 100 times from 1 meter and the average drop time was 1.414 seconds; we therefore estimate $\hat g = 1$ m/s$^2$ by solving the kinematic equation. (Note that this is not ``one gee,'' the gravity of Earth, which is 9.8 m/s$^2$.)

What most of us would do at this point (and what is generally done in the physical sciences, after being told to be careful about it in the first labs class one takes in the freshman year) is to plug that estimate into the formula as if it was the true value of the parameter $g$, so:

\[\hat t(h;\hat g) = \sqrt{2h/\hat g}.\]

(What the instructors for the freshman labs classes say at this point is to track the precision of the measurement instruments and not to be more certain of the calculations than that precision would justify. This is promptly forgotten by everyone, including the instructor.)

So far everything is proceeding as normal, and this is the point where the Bayesians start tut-tutting the frequentists.


When parameters really are random variables

The $\hat g$ we're plugging into the $\hat t$ formula is a function of the data $\hat g = \hat g(D)$ and the data is a set of random variables, as experimental stochastic disturbances, including those inside the measurement apparatus (the person operation the stopwatch, for example) create differences between the measured quantity and the theory.

So, if $\hat g$ is a function of random variables, it is itself a random variable, not a constant parameter.

(Well, duh!, says Fred the Frequentist, unaware of the upcoming trap.)

Now, by the same logic, if $\hat t(h;\hat g)$ is a function of a random variable, $\hat g$, then $\hat t$ is also a random variable, and if we want to compute a time for a given drop from height $h$, it has to be an estimated time, in other words, the expected value of $\hat t(h;\hat g)$,

\[E\left[\hat t(h;\hat g)\right] = \int_{-\infty}^{+\infty}  \sqrt{2h/x} \, f_{\hat g}(x) \, dx\]

where $f_{\hat g}(x)$ is the probability density function for the random variable $\hat g$ evaluated at point $\hat g = x$.

(Huh... erm... says Fred the Frequentist, now aware of the trapdoor open beneath his mathematical feet.)

We can use a Taylor expansion on the function $\hat t(h;x)$ around $\hat g$ to get:

\[\sqrt{2h/x} =  \sqrt{2h/\hat g}  - \frac{\sqrt{h}}{\sqrt{2 \hat{g}^3}} \times (x- \hat g) + O(x^2)\]

Where $O(x^2)$ are higher-order terms that we'll ignore for simplicity. Replacing that expansion into the expected time formula, we get

\[E\left[\hat t(h;\hat g)\right] =  \sqrt{2h/\hat g}  -  \int_{-\infty}^{+\infty} \frac{\sqrt{h}}{\sqrt{2 \hat{g}^3}} \times (x- \hat g) \, f_{\hat g}(x) \, dx \quad + \cdots\]

And when we compare that with the frequentist formula we note that the first term is the same (because it's a constant, the integral just adds up to one), but there's a bunch of other terms missing in the frequentist formula. Those terms correct for the effects of randomness in the running of experiments.

Despite the minus sign, the second term is actually positive because we integrate over the distribution for $\hat g$, which is positively skewed (with more probability mass for the $x$ below the mean of $\hat g$ than above), which means that using the naif estimate, Fred the Frequentist would underestimate the drop times.

But the main point is that Fred the Frequentist would always be wrong.


But wait, there's more!

It gets worse, much worse. 

Let's go back to that measurement from $h=1$ in a planet with $g =1$.

Data points are measured with error. That error, allegedly for a variety of the reasons that statistics instructors enumerate but in reality because it's convenient, is assumed Normally distributed with mean zero and some variance. Let's call it $\epsilon_i$ for each measurement $t_i$ (all for the same test height of one meter), so that

\[t_i = t + \epsilon_i\]

where $t = \sqrt{2/g}$ is the theoretical time for a one meter drop if there were no error and we knew the true $g$; with the numbers we're using here, $t= 1.414$ seconds.

How does Fred the Frequentist usually estimate the $\hat g$ from the $t_i$? Using the kinematics formula, we know that $g = 2h/t^2$, so the "obvious" thing to do is to compute

\[\hat g = 1/N \, \sum_{i} 2h/t_{i}^2\]

where $N$ is the number of drops in an experiment, and then to treat $\hat g$ as a constant when using it in the theoretical formula (as seen above) and as a Normal distributed variable for testing and confidence interval purposes.

Oh, wait a minute. 

A sum of Normal random variables is a Normal random variable. But there's a inverse square in the $\hat g$ sum: $2h/t_{i}^2$. And since $t_i = t + \epsilon_i$, the square alone is going to have both a constant $t^2 = 2$ term and two random variables: $2 t \epsilon_i = 2.828 \epsilon_i $, which is Normal, and $\epsilon_i^2$, which is not. And then there's the inverse part.

So, $\hat g$ is a random variable that is the sum of the inverses of the sum of a constant $2$, a Normal random variable, $2.828 \epsilon_i$, and a non-Normal random variable $\epsilon_i^2$. $\hat g$ is not a Normal random variable, in other words.


The figure shows the distribution of 10,000 estimates of $\hat g$ obtained by simulating, for each, 100 drops from 1 meter, with an $\epsilon_i$ Normally distributed with mean zero and variance 0.5, and using the simulated times to compute a $\hat g$ for that experiment. Doing that 10,000 times we see a distribution of values for the $\hat g$, characterized by two main properties: it is biased up (the true $g$ is 1, the mean of the $\hat g$ is 1.1); and the distribution is positively skewed, with a long tail on the right side, not Normal.

(The discrete plot appears negatively skewed with a right tail, which is weird; the tail is real, the apparently reversed skew is an artifact of the discreteness of the histogram bins. The mean above the median confirms the positive skewness.)

Pretty much all the testing done using standard tests (i.e. dependent on the assumption of Normality for the $\hat g$ result) is done ignoring these transformations. 

This happens a lot in business, when observed variables are turned into indices, for example KPIs, and then these indices are treated, for testing and confidence interval purposes, as if they were Normal random variables. (It also happens in some fields in academe, but horse, dead, flogging...)


Okay, there's a weak response from Fred the Frequentist

The typical counter of Frequentists to Bayesians is that the latter have to make a lot of assumptions to estimate models, and some of those assumptions are not very easy to justify in terms that don't sound suspiciously like ``this particular distribution happens to make the calculus simpler.''

Still, there's no getting around the problems of using point estimates as if they were real parameters and using tests devised for Normally distributed variables on indices that are nothing like Normal random variables.

And that's on the frequentists.

Sunday, August 30, 2020

Fun with geekage for August 2020

Technical fields aren't like other fields.

But there's a disturbing trend in education (brought in from non-technical fields) and in the reporting of technical fields (done by people with minimal-to-none interest in the technical matters, and yes, that includes those with putative training in the technical fields whose work is now in the infotainment business) of moving away from technical knowledge even in those technical fields:


The answers to the type 2 questions, real technical questions, from the top:

First question: The combustion equation would be

CH$_4$ + 2 O$_2$ $\rightarrow$ CO$_2$ + 2 H$_2$O

but it's unnecessary; since each methane molecule will yield a CO$_2$ molecule we can simply calculate the ratio of the masses: m(CO$_2$)/m(CH$_4$) = (12+2*16)/(12+4) = 44/16 = 2.75, so a metric ton of methane will yield 2.75 metric tons of carbon dioxide.

Second question: The density of air at one standard atmosphere and 19°C is 1.225 kg/m$^3$, so a 25 m$^3$ room contains 30.625 kg of air. A 1000 W heating element releases 3.6 MJ of energy in one hour. The increase in temperature is therefore (3600 kJ)/(30.625 kg x 0.72 kJ/(kg °K)) = 163 °K, for a final temperature of 182°C.

(Assuming no losses to the outside and using a constant value for the isochoric specific heat for air throughout the temperature range 0-200°C to avoid computing an integral, a reasonable approximation given it varies between 0.70 and 0.74 in that range.)

Third question: At resonance frequency  $wL = 1/(wC)$ so $w^2 = 1/(LC)$, $w = 57,735$ radian/s or f = 9189 Hz. At that frequency the capacitor and inductor cancel each other out (impedance is zero and power factor is 1), so peak power is $5^2/100 = 250$ mW and RMS power is $250/\sqrt{2}$ = 177 mW.

These are not "gotcha" questions: I learned to solve the second in 11th grade; I learned electronics and chemistry by myself as a kid, but the material to solve the first was taught in 9th grade and the third in 11th grade, for students taking a chemical or electronics track in high-school (9th-12th grades). All of this was assumed known for incoming EECS students in the early 80s in Portugal.


Tempora mutantur, nos et mutamur in illis


From a video of an event in 2016. Most of the weight loss happened in the last 12 months as the result of intermittent fasting and a focus on high-protein, low-energy foods.


Another growth industry in San Francisco


When authors want to be science-y, but don't want to do the science…


From a mil-fic book that we'll keep unnamed.

At 18 km altitude, the gravity is 99.4% of the gravity at sea level ($6378^2/(6378+18)^2$), so Colonel Z would need super-human perception to be able to separate that $0.006 g$ from the turbulence and change in aircraft acceleration due to atmospheric changes.

(The story itself makes little sense, it's a remake semi-update of Tom Clancy's "Red Storm Rising," but with several errors of logic and biased by the need to make Russians super-hyper-badissimo-evil idiots.)


Chocolate milk, the high Protein-to-Energy version


Geeky linkage


(Because work has gotten into the way of blogging, social media, and other things. Book is 90-95% complete.)


Claustrophobia-inducing video by Smarter Every Day crawling inside a torpedo tube in a submarine while it's under the Arctic Ice Cap.


Nasa makes Einstein-Bose condensates aboard the ISS.


Scott Manley showcases the ideal villain lair, complete with a rocket to take the villain to a secret space base. Or a smart way to use the oceans to position a launch pad precisely where one wants (on the Equator, for example, to minimize the energy necessary to change the inclination of the orbit for a GEO satellite).


Because a real geek needs some sci- fi in their life.

Sunday, July 26, 2020

Fun with geekage for July 26, 2020

Yet another "collected tweets" blog post, as I finish up a project. Regular blogging to resume at some point in the future.


Reading too much into a tweet or just being thorough


One of these things is not like the others.


Average cost per gigabyte isn't my only criterion, so I might get the 512 GB drive


Tesla is totally about technology, not subsidy farming. Really really really.


Massimo Bottura is a bit confusing.


Two nice boats by Sausalito

Saturday, July 4, 2020

Fun with geekage for July 4th, 2020

Been busy with book writing (another short book in the works while I wait for advance readers feedback on the numbers book; less math more management), so no time to blog. Some images from my Twitter for now.


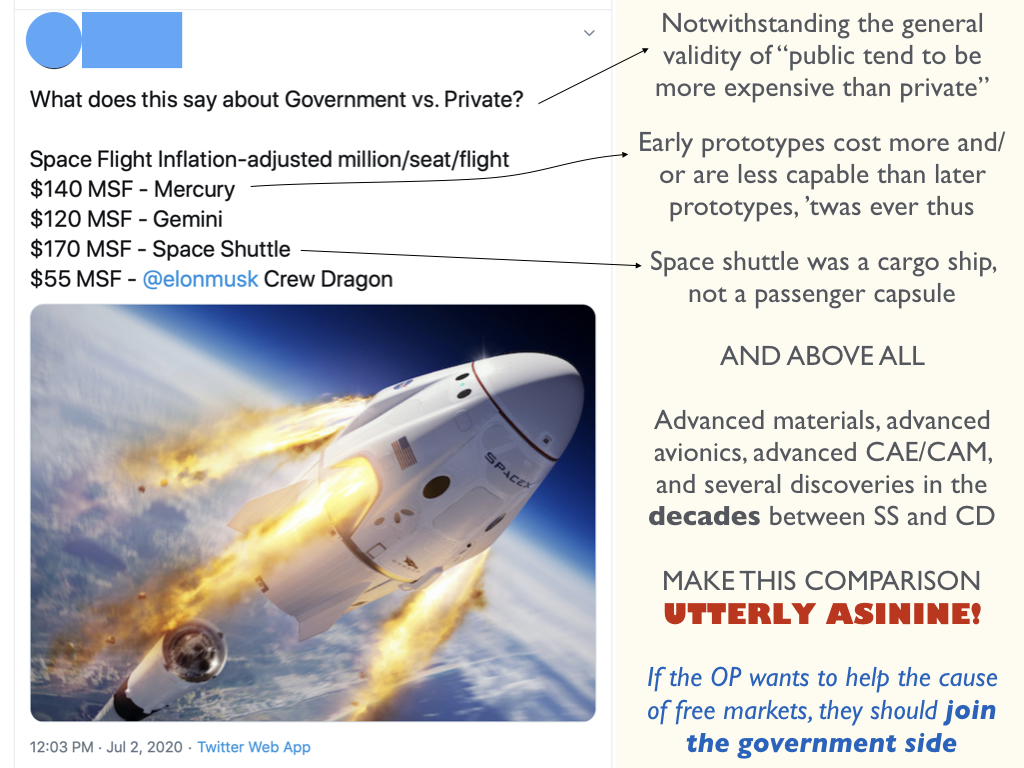
When someone putatively supports one side (free markets) but uses such a flawed and weak argument, I recommend they wholeheartedly join the other side. This level of fail almost suggests it's a false flag.


A bit steep for me.


I find myself agreeing with and extending Yanis Varoufakis.


While getting some of YV's books in audible form for travel and rowing, I realized that maybe Audible's search engine has some pathologies...


Trying a new yogurt I found at Whole Paycheck, ahem, Foods. Those live cultures help with 'le transit intestinal' as the French say. Obs: 1. very pricey; 2. P:E ratio 2/3 (low for yogurt); and 3. Inconsistent message. Taste: 7/10, will buy again.


From a site that has "engineering" in its title. Apparently not engineering enough for its writers to do basic (middle-school) physics. Relying on the NYT for physics is like using a chocolate frying pan. Behold:


Note that at Mach 15, around 5 km/s the energy density of a projectile is 12.5 MJ/kg (~ 3 times that of TNT), so the first sentence only makes sense for a impactor of around 1 to 3 tons. (More feasible that 100 tons, at least.)


Audiophiles aren't, in general, audiophools. There's some foolishness in the wings, but mostly what people who criticize us don't like is that we have taste and discernment.